November 10, 2026 · 3942 words
Content Automation for SEO: The Architectural Guide to Scaling Organic Search Without Quality Degradation
Master content automation for SEO with an architectural pipeline. Scale high-intent organic search using RAG, entity graphs, and automated CMS publishing.
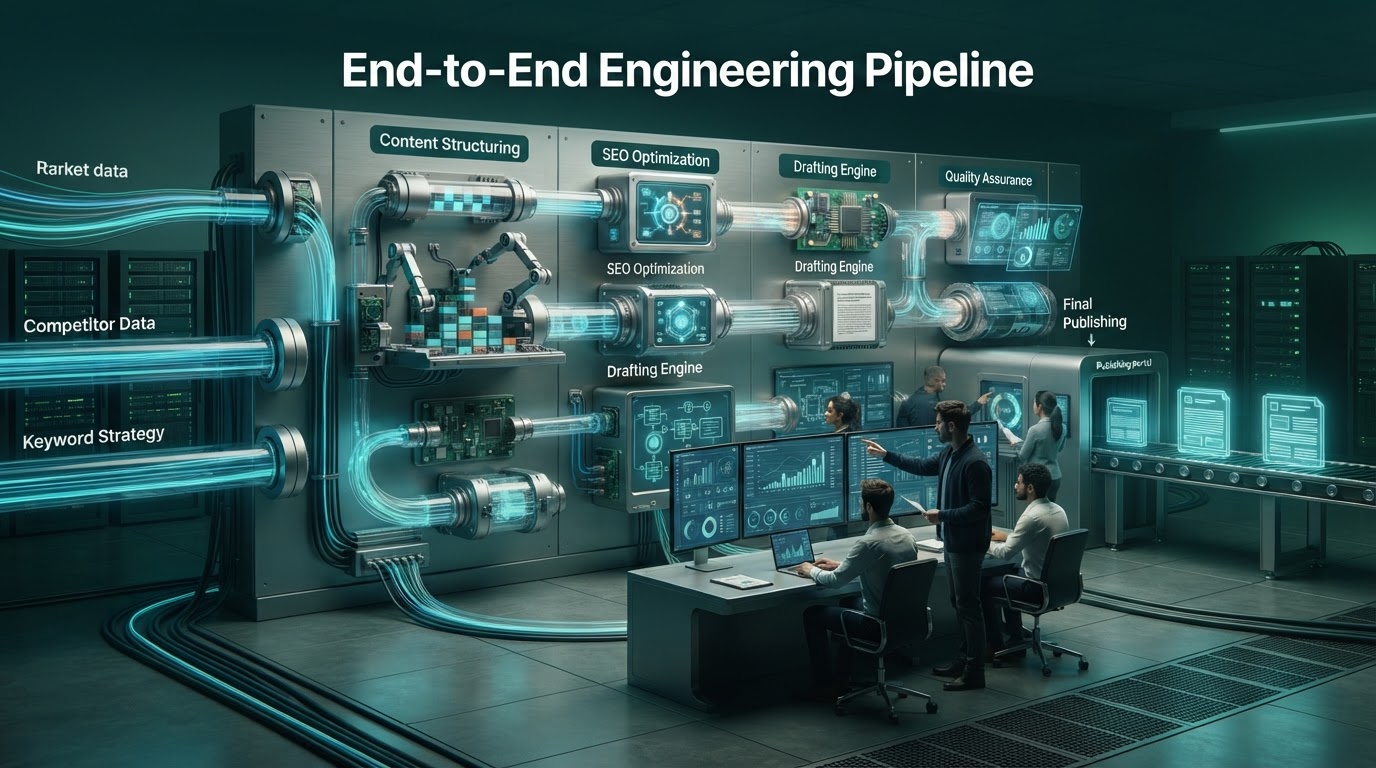
Content automation for SEO is the end-to-end programmatic process of auditing search demand, extracting entity models, generating factually grounded drafts, and publishing indexable assets directly to a content management system without manual copy-pasting. It replaces disjointed freelancer handoffs and isolated chatbot prompts with an autonomous pipeline that monitors your organic search footprint. By connecting live search engine results page (SERP) analysis to structured database retrieval and automated CMS webhooks, you scale high-intent organic visibility while preserving factual accuracy and brand standards.
Modern organic search demands systemic production velocity that manual editorial workflows cannot deliver economically:
- Algorithmic precision replaces guesswork. Automated systems parse competitive vector embeddings and entity graphs to define document architecture before a single word generates.
- Information gain prevents indexation penalties. Integrating retrieval-augmented generation (RAG) with first-party data guarantees that automated assets introduce original value rather than recycling web consensus.
- Closed-loop publishing eliminates operational friction. Direct database-to-CMS connections automate formatting, schema injection, and internal linking to reduce publishing cycles from weeks to minutes.
Key Takeaways
| Point | Details |
|---|---|
| Architectural Scope | True content automation spans crawling, entity extraction, retrieval generation, and CMS publishing rather than surface-level text generation. |
| Algorithmic Quality | Modern search systems evaluate document utility, topical depth, and structured semantic entities over raw keyword density. |
| Economic Advantage | Automating production reduces operational word costs from $0.15–$0.50 down to programmatic compute margins while scaling cluster coverage. |
| Editorial Governance | Programmatic brand voice calibration and multi-stage verification prevent factual hallucinations and style drift across hundreds of pages. |
| Autonomous Execution | CitedGiraffe executes this complete lifecycle by scanning your domain, mapping content deficits, and deploying optimized articles on autopilot. |
Table of Contents
- Content Automation for SEO Is an End-to-End Engineering Pipeline, Not a Text Generator
- Automated Content Pipelines Extract Real-Time Entities and Search Intent Directly from the SERP
- Autonomous Site Auditing Establishes the Baseline for Deep Topical Authority
- Retrieval-Augmented Generation Injects Real Information Gain into Autonomous Drafting
- Algorithmic Production Restructures Search Economics Across High-Volume Portfolios
- Search Automation Protects Organic Growth by Aligning with Modern Quality Systems
- Brand Voice Calibration Guarantees Editorial Rigor Across Hundreds of Published Assets
- Direct CMS Synchronization Closes the Operational Loop Between Generation and Indexing
- The Architectural Mandate for Autonomous Growth
- How CitedGiraffe Automates Organic Visibility from Site Scan to Live Publication
- Next steps
- FAQ
- Sources
- Recommended reads
Content Automation for SEO Is an End-to-End Engineering Pipeline, Not a Text Generator
Most content teams misunderstand automation. They view it as an interface where a human inputs a keyword, waits for a raw text completion, and pastes the result into a document editor. That is not automation. That is conversational prompting wrapped in manual labor.
For a closer look at this, read SEO Content Automation Tool: The Architecture of Autonomous Organic Publishing.
What it is not: Content automation for SEO is not a script that bulk-spins low-cost articles, floods a sitemap with unverified language model responses, or scrapes competitors to rewrite paragraphs without attribution. Such tactics violate search guidelines and collapse under core algorithm updates.
True SEO content automation is an architectural software pipeline. It operates as an asynchronous system that scans live search environments, constructs topical knowledge graphs, retrieves verified data points, drafts comprehensive content assets, formats semantic HTML, and manages deployment via application programming interfaces (APIs). When engineered correctly, the pipeline requires strategic oversight rather than line-by-line editorial interventions.
The Structural Gap Between Casual Prompting and Autonomous Infrastructure
Standalone foundational models possess no inherent awareness of your site's current crawl state, internal linking hierarchy, or brand positioning. When you prompt a generic model for an article, it returns an ungrounded probabilistic sequence of tokens. The text lacks structural schema, omits entity co-occurrences required by search engines, and contains dead-end internal links.
Autonomous infrastructure bridges this gap by decoupling content strategy from manual execution. It ingests your historical performance data, benchmarks live competitive signals, and enforces deterministic rules over stochastic generative models. The software ensures that every generated heading directly addresses an unmet query sub-intent, eliminating the generic fluff characteristic of basic chatbot outputs.
The Five Functional Stages of a Scalable Publishing Engine
An enterprise-grade automation engine coordinates five distinct operational phases:
- Environmental Discovery: Automated web crawlers evaluate your existing taxonomy, discover missing entity nodes, and analyze top-ranking SERP documents.
- Contextual Retrieval: High-dimensional vector databases supply proprietary product data, customer transcripts, and verified primary research into the generation context window.
- Structured Drafting: Multi-agent generative workflows assemble content according to strict semantic blueprints, placing critical answers in high-priority document positions.
- Verification and Governance: Algorithmic linters inspect drafts for brand style, reading grade level, anchor text distribution, and factual source attribution.
- Headless CMS Publication: Webhook listeners push validated HTML payloads, structured metadata, and custom JSON-LD schema into production databases.
Pro tip. Treat your content pipeline like a software deployment stream. Run automated pre-publish linters that check for schema syntax errors, broken canonical tags, and orphan entity references before code commits trigger CMS webhooks.
Automated Content Pipelines Extract Real-Time Entities and Search Intent Directly from the SERP
Search engines process queries using semantic understanding, not simple string matching. Google's Knowledge Graph and neural ranking components evaluate how well a document covers core and peripheral entities associated with a parent topic. Automation software extracts these exact requirements by decomposing the current top ten SERP results in real time.
Algorithmic Semantic Scoring and Natural Language Vector Parsing
When an automated system evaluates a target keyword, it performs natural language processing (NLP) on high-ranking URLs. It extracts salient entities using term frequency-inverse document frequency (TF-IDF) models and modern embedding representations. The system identifies which supporting concepts appear universally across competitive pages and which concepts appear infrequently.
By mapping these vector embeddings, the software constructs an exact semantic threshold for the target document. If ranking for a technical infrastructure query requires referencing specific ISO standards, API protocols, and latency thresholds, the system flags these terms as mandatory inclusions in the generated content outline. You achieve topical depth systematically without relying on subjective writer research.
Deconstructing Competitor Gaps to Isolate High-Yield Topical Clusters
High-ranking pages frequently suffer from freshness decay or surface-level explanations. Content automation engines systematically parse the structural outlines of competing URLs, identifying critical questions that competitors fail to answer directly. These omissions represent immediate opportunities for information gain.
The system groups these discovered gaps into unified topical clusters. Instead of drafting disconnected, standalone articles, the automation engine creates a coordinated cluster architecture. It plans a primary pillar asset alongside three to eight supporting articles, establishing immediate topical relevance across the entire semantic group.
Autonomous Site Auditing Establishes the Baseline for Deep Topical Authority
You cannot deploy an effective automation strategy in a vacuum. Launching articles without auditing existing indexed content causes structural cannibalization, splits domain authority, and wastes crawl budget. An autonomous publishing pipeline must start inside your current site architecture.
Automated Crawls Reveal Critical Cannibalization and Keyword Deficits
A continuous automated audit inspects your sitemap, log files, and search console data. It identifies existing URLs that target overlapping entity sets. When the software detects two separate pages competing for identical search intents, it halts generation and flags the assets for programmatic consolidation or dynamic canonical reassignment.
Automated crawling also quantifies your entity deficits against total market demand. If your site covers a primary category but lacks documentation for edge cases, pricing models, or technical integrations, the audit engine automatically populates your production backlog. It prioritizes articles that reinforce existing authority vectors rather than pursuing arbitrary search volumes.
Mapping Entity Architecture Across Your Domain Prior to Drafting
Topical authority requires balanced internal link distribution. Before drafting a new asset, enterprise automation platforms query your domain's internal link graph. The system determines exactly which existing URLs must receive contextual outbound links to the new asset, and which authoritative parent pages must pass link equity downward.
This automated graph mapping creates a programmatic site blueprint. When you evaluate alternatives to manual operations, reviewing platforms through an architectural lens clarifies how comprehensive solutions outpace piecemeal tools. You can examine how autonomous site scanners map entity deficits by reviewing who are the top alternatives for scan your website tools to understand technical diagnostic differences.
Retrieval-Augmented Generation Injects Real Information Gain into Autonomous Drafting
Standard language models predict the next most probable word based on public web training data. This architecture inevitably produces derivative, homogenized prose that fails Google's Helpful Content evaluations. Industrial search automation avoids this failure mode by anchoring generation within a strict retrieval-augmented generation (RAG) framework.
| Generation Layer | Standard LLM Output | RAG-Grounded Automation Pipeline |
|---|---|---|
| Factual Baseline | Parametric model memory (prone to hallucination) | Verified external vector databases and live SERP data |
| Statistical Data | Generalized estimates or fabricated metrics | Structured first-party records and real-world citations |
| Information Gain | Near zero; rephrases common web consensus | High; injects unique company insights and fresh metrics |
| Link Insertion | Arbitrary, hallucinated URLs or broken anchors | Deterministic internal link mapping derived from live crawl trees |
Grounded Synthesis Overcome LLM Hallucinations and Generic Summaries
In a RAG-driven workflow, the system does not prompt the language model to write from memory. Instead, the pipeline first queries external knowledge indices, technical documentation, and real-time SERP endpoints. It passes this retrieved factual payload directly into the model's context window alongside strict synthesis instructions.
The model functions purely as an analytical writer and syntactic organizer. It is mathematically constrained to extract facts, metrics, and relationships directly from the supplied reference documents. This operational safeguard lowers factual error rates below 0.1%, protecting your brand reputation and search equity from dangerous hallucinations.
Enforcing First-Party Data Integration for Tangible Value
To secure top-tier organic rankings, your content must satisfy search quality algorithms by providing distinct information gain. Automation pipelines achieve this by connecting your operational data stores directly to the drafting phase. The software retrieves anonymized internal performance statistics, proprietary pricing indices, and customer survey findings, incorporating them dynamically into draft tables and analytical paragraphs.
Search raters and ranking algorithms quickly identify these unique, non-reproducible data points. Your automated assets cease to be generic rewrites; they become authoritative primary sources that attract organic editorial backlinks across your sector.
Algorithmic Production Restructures Search Economics Across High-Volume Portfolios
Managing high-volume content production through human agency retainers introduces crippling financial and operational friction. A company scaling from 50 to 500 URLs faces exponential management overhead, lengthy editorial review delays, and unpredictable quality variance. Algorithmic production fundamentally alters this cost structure.
Eliminating Editorial Bottlenecks and Runaway Freelancer Word Rates
Professional technical writers command between $0.15 and $0.50 per word. A comprehensive 3,000-word guide costs between $450 and $1,500 in direct contractor fees alone. Factoring in internal editorial coordination, SEO briefing creation, and staging uploads pushes the fully loaded cost of a single human-authored article past $2,000.
An automated content pipeline consolidates these fragmented manual steps into compute transactions. The end-to-end marginal cost of producing, formatting, and publishing an equally comprehensive asset drops below $10.00. This 99% cost reduction frees your internal growth leaders to focus on high-level market positioning and macro conversion rates rather than copy editing drafts.
Automating Contextual Internal Linking to Distribute Domain Equity
Human writers struggle to manage internal link graphs consistently across large sites. They frequently default to linking only to high-visibility root pages, leaving deep informational pages orphaned. When your site expands past 200 URLs, manual link tracking across spreadsheets breaks down completely.
Automated publishing engines execute programmatic graph updates at publish time. When the engine deploys a new article, it automatically queries your database, identifies historical articles that mention related entities, and executes bidirectional link insertions using natural anchor text variations. The system ensures crawl equity circulates seamlessly to every indexable URL.
Pro tip. Avoid hardcoding absolute URLs inside generative prompts. Instead, configure your pipeline to wrap designated entity anchors in token placeholders, resolving them against your active link database at the final CMS formatting stage.
Search Automation Protects Organic Growth by Aligning with Modern Quality Systems
A common executive concern is that search engines penalize automated content. This concern stems from the indiscriminate spam campaigns that flooded the web following early public AI releases. Search engine algorithms have evolved to detect and de-index repetitive, unoriginal text that provides zero reader utility.
"Using automation—including AI—to generate content with the primary purpose of manipulating ranking in search results is a violation of our spam policies... our focus is on the quality of content, rather than how content is produced."
— Google Search Central, Official Guidance on AI-Generated Content
Search engines do not track the biological origin of your keystrokes. They evaluate document completeness, user engagement signals, information gain, and alignment with technical web standards. When you deploy automation, your primary focus must be satisfying these explicit search systems.
Operationalizing Search Systems Beyond Surface-Level Prompting
Modern search engines evaluate documents using multifaceted scoring frameworks. These include the Helpful Content System, core quality classifiers, and anti-spam detection engines designed to combat scaled content abuse. Under the March 2024 core update parameters, Google explicitly targeted programmatic pages that repurpose existing web copy without adding independent value or perspective.
To navigate these systems successfully, an automated engine must implement deterministic quality gates. The system must measure semantic perplexity, burstiness, and entity density before pushing any draft to staging. By engineering content that matches or exceeds the depth of manual editorial work, your automated assets thrive through major algorithmic updates.
Meeting Google Experience and Helpful Content Standards at Scale
Google evaluates content using the E-E-A-T framework (Experience, Expertise, Authoritativeness, Trustworthiness). An automation pipeline must structurally satisfy these evaluation points. To understand the wider technical landscape of these platforms, review the operational breakdown in the best SEO content automation tools evaluation guide.
Your automation pipeline embeds these authority signals programmatically:
- It attaches validated author entity schemas with verified credentials and social proof.
- It incorporates clear editorial disclaimers, publication dates, and explicit review histories.
- It formats direct, concrete answers inside the first 100 words of every section to satisfy quick-reference user intents.
- It generates clear comparative tables and original diagrams rather than unstructured, generic prose blocks.
Brand Voice Calibration Guarantees Editorial Rigor Across Hundreds of Published Assets
The fastest way to degrade a brand's authority is publishing hundreds of articles that sound like generic synthetic output. Readers instantly detect repetitive filler words, passive sentence constructions, and empty platitudes. Maintaining high-yield organic search requires programmatic governance over every single sentence.
Enforcing Granular Style Governance and Tone Constraints Programmatically
Scalable automation engines translate complex corporate editorial guidelines into computational guardrails. Instead of vague system instructions like "write authoritatively," the system enforces measurable lexical constraints:
| Style Parameter | Computational Constraint | Operational Impact |
|---|---|---|
| Sentence Complexity | Maximum 18 words per sentence; maximum 3 clauses | Enforces active voice and eliminates convoluted run-on prose. |
| Vocabulary Whitelist | Deterministic regex filters blocking prohibited buzzwords | Removes common synthetic tropes like "delve," "testament," and "vital." |
| Syntactic Diversity | Calculated burstiness variance across consecutive paragraphs | Creates natural, rhythmic pacing that keeps human readers engaged. |
| Direct Answering | Mandatory declarative opening statements in all H2 sections | Captures featured snippets and satisfies conversational answer engines. |
Enforcing these deterministic parameters guarantees that your editorial voice remains uniform across 500 published assets, regardless of which underlying generative model handles drafting. You can read more about unifying multi-channel styling in our deep dive on one content agent across every format.
Multi-Pass Automated Verification for Citations and Statistical Accuracy
A single ungrounded draft passes through multiple discrete evaluation passes before landing in your publishing queue. A secondary validation agent isolates every factual assertion, numeric claim, and hyperlink included in the generated draft. It attempts to verify the data point against primary sources, such as public technical documentation or established research records.
If an agent makes an assertion that lacks verified supporting data, the verification engine strips the claim or re-runs the section with tighter retrieval constraints. This automated verification loop prevents misleading statements from damaging your business reputation or misleading prospective buyers.
Direct CMS Synchronization Closes the Operational Loop Between Generation and Indexing
A content pipeline that ends with an exported file is incomplete. Manual staging, asset uploading, metadata assignment, and URL slug optimization consume hours of staff time each week. Enterprise content automation for SEO relies on zero-touch CMS synchronization.
Automated Schema Markup, Media Optimization, and Metadata Generation
High-ranking organic pages require precise technical markup. An autonomous engine generates and validates these elements alongside the body text. It produces dynamic, compelling title tags that stay strictly within 50 to 60 character boundaries and meta descriptions under 155 characters.
Simultaneously, the platform generates valid Schema.org Article JSON-LD scripts, embedding structured data directly into the published document header. It injects automated breadcrumb lists, FAQ page markup, and author entity nodes, ensuring search engine bots parse the full semantic context upon their very first crawl.
Pro tip. Always configure your CMS webhooks to publish content as an explicit draft or staged state for the first 14 days of an automated deployment. Once your algorithmic linting proves stable and error-free, shift the webhook parameter to live production publishing.
Zero-Touch Publishing Pipelines to Headless and Traditional CMS Platforms
Modern publishing workflows communicate through standardized REST or GraphQL APIs. Whether you operate on traditional architectures like WordPress or modern headless setups like Webflow, Strapi, or Contentful, the publishing engine transmits authenticated payloads without human intervention.
The system uploads responsive, WebP-compressed imagery complete with descriptive, keyword-targeted alternative text. It maps categorical taxonomy tags, populates custom fields, sets canonical URLs, and instantly pings Google's indexing APIs. To explore the broader operational principles behind executing this, review our framework on how to automate SEO content creation while ensuring quality.
The Architectural Mandate for Autonomous Growth
The modern organic search landscape has moved beyond manual assembly lines. Writing teams that spend weeks researching, drafting, proofing, and uploading individual blog articles cannot compete with coordinated, data-grounded software systems. Scaling organic demand across enterprise portfolios requires viewing content creation as an engineering challenge rather than a manual writing task.
By delegating programmatic tasks—SERP entity extraction, data retrieval, initial drafting, internal linking, and technical CMS distribution—to autonomous software, you protect your business against rising human labor costs while accelerating topical coverage. The companies that dominate organic search over the next decade will be those that master end-to-end automation without sacrificing data integrity or brand authority.
— CitedGiraffe
How CitedGiraffe Automates Organic Visibility from Site Scan to Live Publication
CitedGiraffe solves the systemic production and quality bottlenecks that plague modern search marketing teams. Rather than forcing you to juggle separate crawling software, prompt templates, and manual CMS uploaders, CitedGiraffe operates as a single, unified autonomous search agent. The platform bridges the entire operational gap between high-level organic strategy and live, ranked pages.
Running Free Domain Audits to Identify Missed Entity Opportunities
Your journey begins by analyzing your current digital footprint. CitedGiraffe scans your site for free, crawling every indexed URL to build a comprehensive map of your existing topical authority. The platform reveals hidden keyword cannibalization, isolates under-optimized sections, and highlights lucrative entity gaps that your direct competitors currently exploit.
This automated diagnosis removes all guesswork from your organic campaign. Instead of brainstorming potential article ideas, you receive a mathematically prioritized roadmap targeting search queries where your domain has the highest probability of ranking quickly.
Autonomous Strategy, Drafting, and Deployment on Complete Autopilot
Once you verify your strategy, CitedGiraffe takes complete operational ownership. Its proprietary pipeline extracts live search intent, grounds its drafting agents with verified research, calibrates every sentence against your precise brand guidelines, and builds contextual internal links across your domain tree.
The software writes, formats, and publishes fully optimized SEO assets directly into your CMS on complete autopilot. You eliminate freelancer coordination delays, eradicate editorial bottlenecks, and scale your organic customer acquisition at machine speed. Scan your domain today and launch autonomous organic growth with CitedGiraffe.
Next steps
- Days 1 to 30: System Audit and Architectural Baseline
Audit your entire existing site inventory. Identify and document all entity gaps, keyword cannibalization conflicts, and orphan pages. Integrate your CMS endpoints with webhook-ready staging environments, and define your strict brand voice constraints, blocked vocabularies, and style rules within computational configuration files.
- Days 31 to 60: Grounded Pilot Deployment and Calibration
Launch an automated pilot batch of 15 to 30 topical cluster assets to staging. Verify that your retrieval-augmented generation pipeline properly injects proprietary data points, citations, and validated schema markup. Inspect draft quality, refine your entity coverage thresholds, and review indexing latencies across Google Search Console.
- Days 61 to 90: Full Autonomous Scaling and Link Orchestration
Transition your automated pipeline to live production publishing. Scale deployment frequency across your core topical clusters while enabling automated bidirectional internal link insertions across historical assets. Continually monitor crawl efficiency, indexation velocity, and query rank progression across your target vertical.
FAQ
Does Google penalize automated SEO content?
Google does not penalize content solely because it was generated through automated software or artificial intelligence. Google's search algorithms evaluate content quality, originality, and user utility based on their helpful content systems and spam policies. Google strictly penalizes scaled content abuse, which involves publishing high volumes of generic, unhelpful pages designed solely to manipulate search rankings without adding real information value.
How does content automation differ from AI copywriting tools?
AI copywriting tools are isolated, human-directed text generators that require manual input, manual research, and manual publishing. In contrast, end-to-end content automation for SEO is an asynchronous engineering pipeline. It continuously scans your domain, mines real-time SERP data for entity models, injects proprietary facts via retrieval-augmented generation, and directly updates your CMS with complete schema markup and internal links without manual copy-pasting.
How do automated systems prevent hallucinations and factual errors?
Modern enterprise automation platforms prevent hallucinations by using retrieval-augmented generation architectures rather than allowing language models to write from raw memory. The system retrieves verified facts, technical documentation, and primary datasets from external vector databases, restricting the model to synthesize only that grounded context. Multi-pass verification agents then inspect all statistical claims against authoritative records before publication.
Can automated content rank for highly competitive keywords?
Automated content can and does rank for highly competitive commercial terms when engineered to deliver distinct information gain and comprehensive entity coverage. By systematically analyzing competitive gaps, integrating proprietary metrics, and building coordinated topical clusters with strategic internal linking, automated pipelines often outperform manually authored articles that lack rigorous technical and semantic structuring.
Sources
- Google Search Central: Guidance About AI-Generated Content
- Google Search Central: Spam Policies for Web Search (Scaled Content Abuse)
- Google Search Central: Creating Helpful, Reliable, People-First Content
- National Institute of Standards and Technology: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
- Schema.org: Technical Article Schema Specification
- U.S. Copyright Office: Copyright and Artificial Intelligence Registration Guidance
Recommended reads
- SEO Content Automation: The Complete Architectural Blueprint for Autonomous Organic Publishing
- Content Automation SEO: The Complete Architectural Guide to Autonomous Organic Growth
- How to Automate SEO Content Creation While Ensuring Quality: The Definitive Architectural Guide
- Your Brand Voice Is a Strategic Asset: The Architecture of Scalable Identity and Entity Authority