November 6, 2026 · 4466 words
Content Automation SEO: The Complete Architectural Guide to Autonomous Organic Growth
Scale organic rankings with content automation SEO. Discover how programmatic pipelines, entity grounding, and autonomous publishing drive sustainable growth.
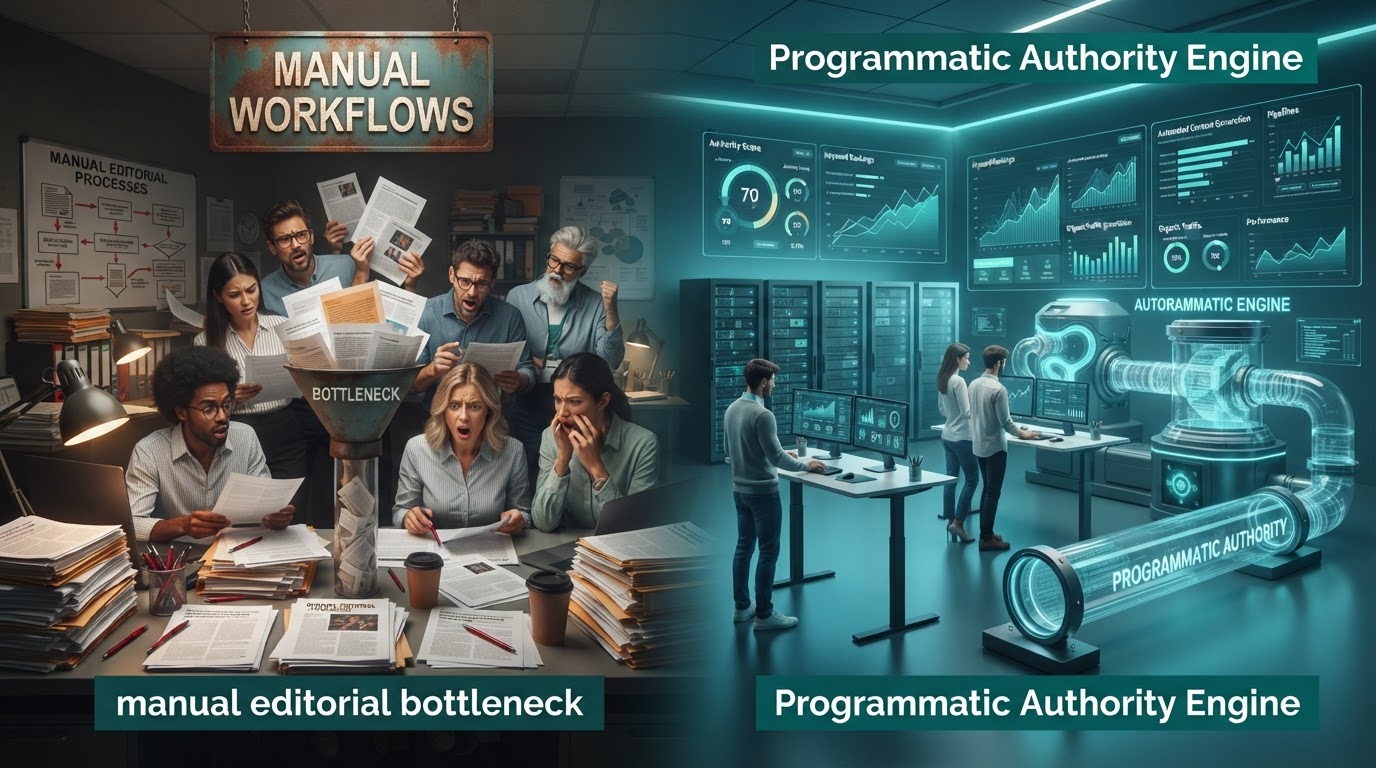
Content automation SEO is the programmatic architecture of analyzing organic search intent, generating factually grounded editorial assets, and orchestrating technical publishing workflows without manual human drafting. When executed at enterprise scale, this system transforms organic search acquisition from a labor-constrained manual bottleneck into a predictable, software-driven pipeline. It continuously scans your domain architecture, detects unaddressed topical clusters, constructs entity-rich content, and manages internal link graphs to capture search visibility across thousands of target queries.
Operating an autonomous publishing engine requires replacing manual editorial guesswork with strict programmatic standards:
- Programmatic gap discovery. Machine-driven domain scans analyze existing content coverage and identify missing keyword clusters before writing begins.
- Entity-first semantic generation. Retrieval-augmented generation grounds every claim in verified data to satisfy modern search engine information gain standards.
- Autonomous CMS publication. Dynamic internal link updates and real-time schema markup injection eliminate manual deployment delays.
Key Takeaways
| Point | Details |
|---|---|
| Strategic Shift | Content automation SEO pivots digital growth from manual, article-by-article creation to an algorithmic, end-to-end publishing infrastructure. |
| Algorithmic Compliance | Google evaluates content on information gain, accuracy, and utility rather than its generation method, rewarding verified entity depth under Search Essentials. |
| Architectural Core | True automation unifies automated site crawling, programmatic intent clustering, retrieval-augmented drafting, and direct CMS delivery. |
| Unit Economics | Automated pipelines lower the production cost per indexed page by 70% to 90% while reducing publishing turnaround from weeks to minutes. |
| CitedGiraffe Advantage | CitedGiraffe executes this complete lifecycle—scanning your site for free, mapping gaps, drafting brand-aligned assets, and publishing autonomously. |
Table of Contents
- Key Takeaways
- Content Automation SEO Replaces Manual Editorial Bottlenecks with Programmatic Authority Engines
- Modern Search Algorithms Prioritize Quantifiable Information Gain over Repetitive Drafting
- The Four Architectural Layers of an Enterprise SEO Content Automation Engine
- Automated Content Production Must Align with Google Search Essentials to Secure Long-Term Indexation
- Entity Salience and Knowledge Graph Grounding Dictate Modern Search Engine Dominance
- Dynamic Internal Link Graph Management Protects Crawl Budget and Funnels Page Equity
- Autonomous Workflows Dramatically Alter Content Unit Economics for In-House Teams and Agencies
- Programmatic Governance Frameworks Maintain Strict Brand Voice and Fact-Checking Standards
- Low-Tier Automation Workflows Trigger Algorithmic Demotion Through Identifiable Structural Flaws
- Why Autonomous Search Architecture Must Supercede Human-in-the-Loop Copywriting — CitedGiraffe
- CitedGiraffe Closes the Automation Loop from Free Initial Site Scan to Hands-Off Autonomous Publishing
- Core Operational Metrics Reveal the True Performance of Automated SEO Deployments
- Next Steps
- FAQ
- Sources
- Recommended Reads
Content Automation SEO Replaces Manual Editorial Bottlenecks with Programmatic Authority Engines
Traditional SEO content production depends on linear, fragmented operations. An SEO strategist audits a domain, extracts raw query data from third-party databases, isolates keyword gaps, and writes a manual brief. A freelance writer interprets the brief, synthesizes surface-level search engine results page (SERP) data, and delivers a draft several days or weeks later. An editor reviews the copy for factual accuracy and tone, and a webmaster manually copies the text into a Content Management System (CMS), configures metadata, uploads images, and adds internal links.
For a closer look at this, read SEO Content Automation: The Complete Architectural Blueprint for Autonomous Organic Publishing.
This legacy process breaks down under competitive search environments. It yields a standard publishing cadence of 4 to 12 long-form pieces per month at a variable cost ranging between $250 and $1,200 per article. At that velocity, covering an enterprise topical map composed of 600 interconnected subtopics requires over four years of consistent production. Competitors operating programmatic authority engines can fully cover the same semantic footprint in under 60 days. The manual operational model cannot maintain parity with modern crawling rates, dynamic SERP shifts, or algorithmic realignments.
What it is not: Content automation SEO is not an unmonitored script that fires basic LLM prompts into a static blog feed. It is not cheap article spinning, scraping RSS feeds, or producing thousands of shallow, repetitive programmatic doorway pages designed to trick crawlers. True automation constitutes a structured programmatic architecture that mirrors the workflows of high-performing editorial, technical, and data science teams simultaneously.
Programmatic SEO automation operationalizes the entire value chain. It continuously scans your existing web presence, maps the relationships between entities across your site, identifies topical blind spots, drafts comprehensive articles through verified knowledge retrieval, and publishes directly into your CMS. By replacing manual handoffs with software rules, you convert search engine optimization from a speculative creative service into an autonomous infrastructure investment.
Modern Search Algorithms Prioritize Quantifiable Information Gain over Repetitive Drafting
Modern information retrieval models no longer rely on simple lexical matching or crude keyword densities. Search ranking systems deploy deep transformer models, knowledge bases, and algorithmic quality classifiers to calculate the exact semantic delta between new content and historical documents already indexed for that query. This mechanism is known as information gain.
If an automated system merely crawls the top 10 search results, combines their sentences, and restructures the points using varied vocabulary, the output delivers zero net information gain. Google holds patents specifically designed to score incoming documents based on how much new, non-redundant information they contribute to a user who has already inspected prior results. When systems detect that a URL contains only derivative information, search engines discount its ranking authority or omit it from primary index tiers entirely.
Pro tip. Integrate internal proprietary data, unique calculations, and primary domain entities into your programmatic templates. If your automated pipeline cannot supply an authoritative fact, statistic, or architectural standard that is missing from the existing SERP, the page fails the information gain threshold.
According to researchers in the paper GEO: Generative Engine Optimization, generative engines and advanced search retrieval architectures favor documents that introduce unique entities, precise statistical evidence, and authoritative source citations. Pages that optimize for entity connectivity and fact density achieve up to 30% to 40% higher relative visibility across automated query summaries than generic, unstructured prose.
Automated SEO engines succeed when they are engineered to retrieve and integrate verifiable data points, technical specifications, and structural taxonomies. Rather than generating text blindly, the platform must query authoritative databases, cross-reference industry documentation, and verify semantic relationships before compiling the final document.
The Four Architectural Layers of an Enterprise SEO Content Automation Engine
A production-ready content automation framework does not rely on a monolithic generative prompt. It functions as a pipeline of four independent yet coordinated software systems. Each layer resolves an operational bottleneck in the organic acquisition lifecycle.
| Layer | System Function | Key Deliverables | Primary Risk Managed |
|---|---|---|---|
| 1. Audit & Discovery | Domain crawling and graph analysis | Entity map, topical gap inventory, cannibalization log | Covering low-value or already saturated queries |
| 2. Intent & Clustering | Lexical decomposition and SERP clustering | Cluster blueprints, parent-child URL hierarchies | Keyword cannibalization and fragmented equity |
| 3. RAG Drafting Engine | Retrieval-augmented content generation | Entity-dense text, data tables, code snippets | Hallucinations and low information gain scores |
| 4. Autonomous CMS Delivery | Headless API delivery and link updating | Rendered HTML, JSON-LD schema, dynamic bidirectional links | Manual upload bottlenecks and orphan page creation |
Automated Site Auditing and Topical Gap Discovery
Before an automation platform drafts a single word, it must understand the existing topical graph of the destination domain. The system crawls your site architecture, parsing published URLs, metadata, schema definitions, and content bodies. It projects your published pages into an internal vector space to evaluate your current topical coverage.
This audit discovers unaddressed search real estate. If your site contains 20 articles on retail inventory management but lacks content addressing warehouse barcode scanning hardware or FIFO reconciliation protocols, the audit module flags these gaps. You avoid redundant production because the system recognizes what you already cover. Teams exploring scalable workflows can review our breakdown of AI SEO automation workflows to see how auditing fits into broader orchestration strategies.
Programmatic Search Intent Mapping and Query Clustering
Unstructured keyword lists produce cannibalization when deployed across autonomous publishing tools. If an engine writes five distinct articles targeting "content automation software," "automated content tools," "SEO automation platforms," "content writing automation," and "automated SEO writing," these assets compete against each other for the same ranking footprint.
An enterprise engine groups target keywords based on SERP overlap. If the live search results for Query A and Query B share 4 or more identical URLs in the top 10 positions, the engine clusters them under a single master intent. It assigns one primary entity, establishes a definitive target canonical path, and maps secondary search variations as subheadings within the master outline. This prevents ranking volatility and consolidates search authority onto a single high-performing asset.
Retrieval-Augmented Generation for Verified Entity-Rich Drafting
Standard language models generate probable sequences of words based on training weights. When questioned about complex technical domains, they hallucinate release dates, misstate technical parameters, and invent non-existent features. In an automated SEO context, this produces low-quality content that damages user trust and risks regulatory scrutiny under FTC guidance on deceptive AI representations.
Retrieval-Augmented Generation (RAG) resolves this failure mode. When drafting, the engine searches validated vector stores, industry research papers, standards documentation, and your brand's unique positioning briefs. The model is strictly instructed to assemble its explanations using only retrieved, verifiable facts. The drafting system matches your brand tone, embeds semantic entities recognized by search engine knowledge graphs, and outputs factual, technically accurate information.
Autonomous CMS Publishing and Dynamic Internal Link Integration
Draft generation provides zero search return until the output is rendered live on an indexable URL. Manual formatting, image optimization, schema creation, and publishing consume significant operational hours. An enterprise engine bypasses this step entirely by interacting directly with CMS application programming interfaces (APIs) such as WordPress, Webflow, Shopify, or custom headless endpoints.
The system generates clean HTML, structured comparison tables, code blocks, and compliant Schema.org Article structured data. Simultaneously, the internal linking engine updates. It analyzes historical pages across your domain, identifies semantically relevant anchor text opportunities, and dynamically inserts bidirectional links pointing directly to the newly published URL. The new page enters the search ecosystem with existing internal link equity and zero human intervention.
Automated Content Production Must Align with Google Search Essentials to Secure Long-Term Indexation
A common misconception across organic search marketing is that Google penalizes content simply because it was created using automated software. Google has publicly clarified its engineering stance on multiple occasions. The search engine evaluates the utility, depth, and helpfulness of a page, not the specific medium of its creation.
"Our focus on the quality of content, rather than how content is produced, is a useful guide that has helped us deliver reliable, high quality results to users for decades... Using automation—including generative AI—is not against our guidelines."
— Google Search Central, Guidance About AI-Generated Content
Google's official guidance on AI-generated content establishes that automation used to manipulate search rankings violates webmaster guidelines, but automation leveraged to build informative, comprehensive resources is welcome. The platform's enforcement actions target low-effort, mass-produced text that lacks original perspective or clear utility. Their Spam Policies for Google Web Search explicitly outline automated spam as content generated programmatically without regard to user experience, search intent satisfaction, or factual accuracy.
To evaluate if automated production complies with Google quality raters, compare your output against the core tenets established in the Google Search Quality Rater Guidelines. Pages must demonstrate Experience, Expertise, Authoritativeness, and Trustworthiness (E-E-A-T). Trust is the central pillar. If an automated article contains fabricated statistics, vague explanations, or contradictory instructions, quality classifiers categorize the domain as low-tier. Enterprise automation pipelines enforce programmatic guardrails that ensure every generated paragraph adheres to verifiable truths and strict editorial parameters.
Entity Salience and Knowledge Graph Grounding Dictate Modern Search Engine Dominance
Modern search algorithms build representations of the world using entities—distinct, identifiable concepts, people, places, or technical protocols stored within a broader Knowledge Graph. Search engines no longer ask "How many times does the keyword appear on this page?" Instead, they ask "Does this document discuss the necessary related entities that naturally contextualize this subject?"
When an automated workflow approaches a subject like enterprise database replication, it must map the topic's semantic neighborhood. A superficial article might mention "fast database syncing." An entity-dense automated framework will identify and embed the specific nodes required for contextual authority: Write-Ahead Logging (WAL), Change Data Capture (CDC), asynchronous replication lag, round-trip time (RTT), Raft consensus algorithms, and distributed transactions.
Pro tip. Run programmatic natural language processing (NLP) validation against drafts before publishing. Measure the salience scores of key entities to verify they match or exceed the topical depth of top-tier academic or professional reference materials.
Entity salience measures how central a given entity is to the core discourse of the text. If your automated platform generates hundreds of shallow words around an umbrella keyword without anchoring them to validated entity nodes, search engines categorize the page as low-confidence noise. Platforms that understand brand voice and multi-format content synthesis treat entity density as a core architectural requirement, ensuring that every asset reinforces topical depth across your primary domain vectors.
Dynamic Internal Link Graph Management Protects Crawl Budget and Funnels Page Equity
Publishing dozens of automated pages without a programmatic internal link structure isolates your content. Search engine crawlers navigate the web primarily by following hyperlinks. When new pages sit outside the internal link graph, or remain hidden deeper than four clicks from your homepage, spiders discover them slowly or bypass them entirely. In severe cases, up to 35% of an enterprise site's crawl budget is wasted attempting to reach orphan pages.
True content automation software treats internal linking as a live graph calculation rather than an afterthought. The system executes two critical linking directions:
- Upstream parent linking. The newly generated page automatically links back to its parent category pillar, commercial service pages, and primary entity hubs with descriptive, keyword-rich anchor text.
- Downstream reciprocal updating. The automation engine queries your published index via API, identifies older related articles that possess established PageRank, and updates their HTML to link directly downward into the newly created asset.
Dynamic link management transforms isolated blog posts into a cohesive topic cluster. Search crawlers can traverse the entire cluster in a single crawl session, redistributing link equity evenly across your domain and expediting the indexation of new URLs from weeks down to hours.
Autonomous Workflows Dramatically Alter Content Unit Economics for In-House Teams and Agencies
The operational cost structure of manual content production prevents organizations from achieving total topical authority. When you budget between $3,000 and $6,000 per month for organic content, an agency or in-house team typically delivers 5 to 10 articles. Under this model, targeting long-tail queries that yield only 50 to 150 monthly searches is mathematically unviable. The customer acquisition cost (CAC) on low-volume terms cannot justify a $400 upfront human writing cost.
Yet in search aggregate, long-tail queries account for over 70% of total search demand. These specific, high-intent queries convert at rates two to three times higher than generic head terms. Content automation fundamentally shifts these unit economics, making comprehensive long-tail coverage profitable.
| Production Variable | Manual Editorial Operations | Enterprise Autonomous Systems |
|---|---|---|
| Direct Cost Per Article | $250 – $1,200 | $5 – $25 |
| Turnaround Time per Asset | 7 – 21 business days | 3 – 8 minutes |
| Monthly Production Ceiling | 10 – 30 articles | 500 – 2,500+ articles |
| Labor Allocation | Writing, formatting, manual linking | High-level strategy, conversion analysis |
| Long-Tail Query Viability | Only queries with >1,000 monthly volume | Economically viable at 20+ monthly volume |
By dropping direct marginal production costs by over 90%, you can afford to answer every technical question, build dedicated integration landing pages, and capture low-competition niche queries. This structural change frees marketing personnel from repetitive operational execution, allowing them to focus on positioning, value propositions, and bottom-funnel conversion funnels.
Programmatic Governance Frameworks Maintain Strict Brand Voice and Fact-Checking Standards
Deploying automated publishing without architectural governance introduces serious enterprise risk. When brand identity is diluted, consumer trust drops. Organizations must establish programmatic guardrails that enforce voice, styling, and verification standards systematically across every generated paragraph.
Brand governance begins with deterministic style guidelines converted into machine-readable rules. If your company prohibits generic marketing jargon, demands active voice, requires Oxford commas, and mandates specific technical nomenclatures, the automation engine's parsing layer must validate the text against these rules before publishing. If an asset violates a linguistic constraint, the system rejects the draft and re-executes the generative cycle.
Fact-checking requires independent programmatic verification. High-tier automation stacks separate the drafting model from an evaluation model. The second system functions strictly as a compliance reviewer: it extracts every entity, date, mathematical calculation, and technical claim from the draft, searching trusted internal knowledge bases to confirm their accuracy. If a fact cannot be corroborated by a verified source, it is stripped or rewritten automatically. You eliminate human editorial fatigue while preserving professional publication standards.
Low-Tier Automation Workflows Trigger Algorithmic Demotion Through Identifiable Structural Flaws
Organizations that attempt to automate search production using crude, single-prompt scripts encounter predictable algorithmic demotion. Search engine quality filters are engineered to detect patterns of low-effort automation. Understanding these failure states is critical to engineering an engine that endures core algorithm updates.
Factual Drift and Unverified Claims
When an automation tool relies solely on raw language models without RAG architecture, factual drift occurs. The model invents statistics, quotes non-existent industry executives, or fabricates API capabilities. When human users encounter these errors, bounce rates climb and time-on-page metrics collapse. Search quality systems interpret these behavioral signals alongside cross-reference knowledge base checks, leading to systematic site-wide indexation pruning.
Internal Keyword Cannibalization Across Clusters
Uncoordinated publishing scripts frequently generate dozens of URLs that target identical underlying search intents. For instance, generating separate articles for "how to track search intent," "tracking search intent," and "search intent monitoring" forces search engine ranking algorithms to evaluate multiple pages from your domain for the same query. The search engine alternates rankings between your pages, leading to ranking instability and suppressing organic growth across the entire cluster.
Syntactic Homogeneity and Repetitive Structural Boilerplates
Low-grade generators utilize static, hard-coded templates: an introductory paragraph, three identical subheadings with bullet points, and a formulaic concluding paragraph. Search engine parsers easily identify these structural templates across hundreds of pages. If every page on your domain shares the same syntactic rhythm, length, and sentence variation, machine learning classifiers will flag the assets as low-effort programmatic spam under Google Search Essentials.
Pro tip. Introduce dynamic schema variations, variable heading depths, diverse data presentation formats (such as technical tables, callouts, and step-by-step sequences), and fluctuating document lengths across your programmatic pipeline to mirror genuine editorial variety.
Why Autonomous Search Architecture Must Supercede Human-in-the-Loop Copywriting — CitedGiraffe
The organic search landscape is transitioning from manual writing assistance to fully autonomous publication infrastructure. Many software providers continue to advocate for a "human-in-the-loop" model, where an artificial intelligence tool provides an outline or rough draft, and a human marketing manager spends an hour editing, formatting, and uploading the text. We reject this compromise as an inefficient half-measure.
Human-in-the-loop copywriting does not eliminate the editorial bottleneck; it merely shifts the friction from typing words to proofreading them. It preserves the same labor constraints, prevents true programmatic scaling, and fails to solve technical challenges like dynamic internal link graphs, live schema generation, or continuous domain-wide gap discovery. The true value of computational software is not to assist manual workflows, but to systematize and automate them entirely through verifiable engineering standards.
When you build a system with robust retrieval architecture, deterministic brand governance, and programmatic quality gates, software executes factual research, semantic optimization, and technical publishing far more reliably than an exhausted human contractor. Autonomous organic growth is an infrastructure problem. Solving it requires autonomous publishing platforms that run continuously in the background, freeing operators to focus on product development, revenue operations, and customer retention. You can examine how this approach compares across vendors in our evaluation of the best SEO content automation tools available on the market.
CitedGiraffe Closes the Automation Loop from Free Initial Site Scan to Hands-Off Autonomous Publishing
Most content tools stop at text generation, leaving you to handle the hardest parts of SEO operations manually: auditing your technical architecture, finding keyword gaps, mapping search intent, formatting code, and publishing assets. CitedGiraffe resolves this broken pipeline by providing a complete, autonomous organic growth engine.
The journey begins with our comprehensive site scan. Enter your URL, and CitedGiraffe's proprietary diagnostic engine immediately crawls your domain for free. It indexes your existing content, evaluates your entity density, maps your current ranking footprint, and detects critical topical voids where your competitors are capturing organic traffic you should own. You no longer have to spend dozens of hours inside manual spreadsheets or legacy keyword tools guessing what to write next.
Once your topical gaps are mapped, CitedGiraffe takes complete operational control. Our engine plans your editorial calendar, clusters keyword queries to prevent internal cannibalization, and writes deeply researched, factually grounded articles. Every piece incorporates rich semantic entities, optimized heading hierarchies, tailored structured data, and contextually relevant data tables. We maintain strict adherence to your brand voice, ensuring your published assets sound authentic, authoritative, and professional.
Finally, CitedGiraffe manages the publishing cycle on autopilot. Our system connects directly to your CMS via secure integrations. It formats HTML, injects Schema.org markup, generates bidirectional internal links to pass PageRank throughout your domain, and publishes finished assets on the schedule you define. You transform organic search acquisition into a hands-off, programmatic growth channel. If you are comparing operational models, see our analysis of alternatives for scan your website tools to understand how our architecture sets the benchmark.
Stop managing freelance writers, manual editors, and disjointed publishing workflows. Visit CitedGiraffe today, scan your website for free, and let our autonomous engine plan, write, and publish your organic content on complete autopilot.
Core Operational Metrics Reveal the True Performance of Automated SEO Deployments
To confirm that your automated publishing pipeline performs effectively without incurring algorithmic penalties, monitor a distinct set of operational and technical metrics. Evaluating success based solely on gross traffic numbers provides incomplete feedback.
| Operational Metric | Target Performance Benchmark | Diagnostic Significance |
|---|---|---|
| Indexation Velocity | >80% of published URLs indexed within 14 days | Measures crawlability, site architecture health, and absence of low-quality spam flags. |
| Average Information Gain Ratio | >25% unique entity/data points versus SERP average | Verifies that the generation layer avoids derivative content demotion algorithms. |
| Crawl Error Rate | <0.5% 4xx or 5xx status codes during automated runs | Confirms CMS API publishing stability and URL canonicalization accuracy. |
| Internal Link Equity Depth | 100% of new pages within ≤3 hops from domain authority hubs | Ensures crawl efficiency and proper internal distribution of PageRank. |
| Cost Per Organic Visitor (CPOV) | Decreasing by >40% over a 180-day deployment window | Demonstrates unit economic efficiency over manual editorial approaches. |
Tracking these values weekly allows you to identify technical bottlenecks before they impact domain visibility. If indexation velocity stalls, inspect your dynamic internal links and review entity salience across affected clusters. If cost per organic visitor declines according to plan, scale your publishing frequency across adjacent topical verticals.
Next Steps
Transitioning from manual editorial friction to autonomous programmatic SEO requires an organized, time-boxed rollout. Follow this operational roadmap to deploy automation systematically over the next 90 days.
Days 1 to 30: Technical Foundation and Domain Audit
- Execute a full site crawl to document all live URLs, existing ranking keywords, and canonical structures.
- Run a free domain scan on CitedGiraffe to identify unaddressed topical gaps and establish your baseline entity authority score.
- Audit your CMS endpoints and API authentication layers to ensure programmatic publishing compatibility.
- Document your machine-readable brand voice guidelines, specifying prohibited vocabulary, tone attributes, and required structural layouts.
Days 31 to 60: Controlled Pilot Cluster Deployment
- Select one clearly defined, non-cannibalizing topical cluster containing 20 to 50 interconnected informational queries.
- Configure your RAG data retrieval pipelines with relevant product documentation, whitepapers, and authoritative industry databases.
- Deploy the pilot cluster autonomously to your CMS, verifying that bidirectional internal links and Schema.org metadata render accurately.
- Inspect the published URLs in Google Search Console to monitor real-time crawl frequency and indexation progress.
Days 61 to 90: Full Scale Automation and Performance Auditing
- Review the indexation velocity of your pilot cluster, targeting a minimum 80% coverage rate across search engine indexes.
- Expand production across multiple adjacent topic clusters, increasing publishing cadence to scale your organic footprint.
- Monitor search intent stability and query rankings to ensure no cannibalization emerges between parallel clusters.
- Calculate your realized cost per indexed page and adjust topical targeting toward emerging high-intent commercial vectors.
FAQ
What is the difference between programmatic SEO and content automation SEO?
Programmatic SEO historically refers to generating thousands of database-driven landing pages based on static datasets, such as city-specific service pages or directory listings. Content automation SEO incorporates advanced natural language understanding, retrieval-augmented generation, and semantic entity mapping to produce comprehensive, long-form editorial guides, technical explanations, and contextual analyses that satisfy complex informational search intent at enterprise scale.
Will Google penalize my website for using automated SEO content?
No, Google does not issue algorithmic penalties based on the use of automation or generative tools. Google enforces policies against low-quality, spammy content that lacks information gain, contains unverified claims, or exists solely to manipulate search rankings. Content that provides verified factual depth, addresses search intent, and follows Google Search Essentials will rank effectively regardless of whether a human or an automated system authored it.
How does content automation handle internal linking effectively?
An enterprise content automation system treats internal linking as a dynamic graph problem. When publishing a new article, the engine identifies relevant parent pillars and sibling pages within the cluster, generating context-rich contextual hyperlinks. Furthermore, the engine queries existing site content through CMS APIs and automatically updates older, high-authority pages to point directly back to the newly published asset, preserving crawl paths and distributing PageRank efficiently.
Can automated content match our specific brand voice and technical standards?
Yes, modern autonomous engines achieve brand voice alignment through structured governance frameworks. By converting your editorial style guides, vocabulary constraints, and technical terminologies into deterministic programmatic rules, the system inspects every generated draft before publication. Combined with retrieval-augmented generation, the engine grounds every claim in your validated brand knowledge bases, eliminating hallucinations and ensuring technical accuracy across every post.
Sources
- Google Search Central: Guidance About AI-Generated Content
- Google Search Central: Spam Policies for Google Web Search
- Google: Search Quality Rater Guidelines
- arXiv: GEO: Generative Engine Optimization
- Schema.org: Article Vocabulary Specification
- Federal Trade Commission: Keep Your AI Claims in Check
Recommended Reads
- Streamline Your Strategy: The Power of AI SEO Automation Workflows
- What Are the Best SEO Content Automation Tools Available Right Now?
- One Content Agent. Every Format. Your Brand Voice: Unpacking CitedGiraffe's Core Promise
- Who Are the Top Alternatives for 'Scan Your' Website Tools? (CitedGiraffe vs. Competitors)