November 2, 2026 · 3998 words
See How AI Talks About Any Brand: A Diagnostic Guide to Auditing Generative Perception and Entity Authority
See how AI talks about any brand. Learn how to audit generative perception, RAG pipelines, and entity authority to measure citations and resolve drift.
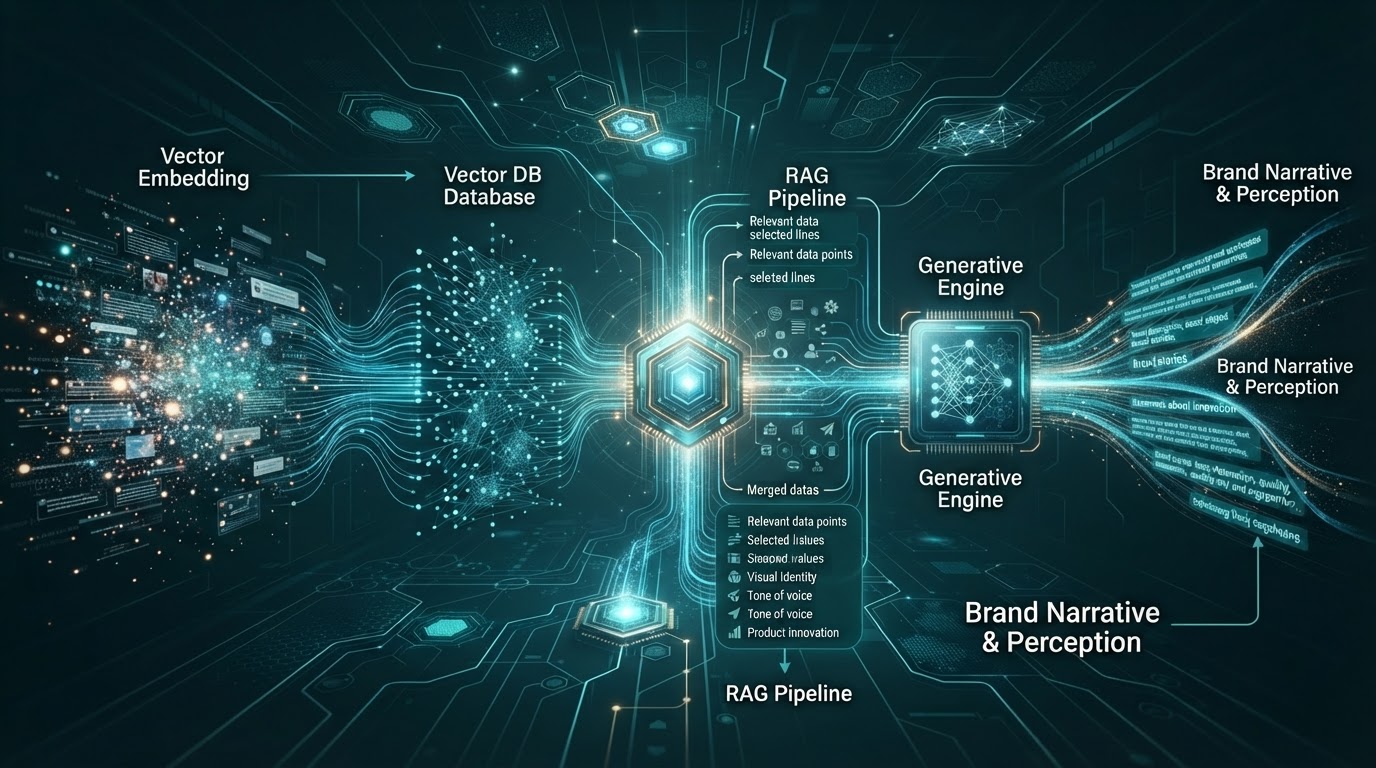
To see how AI talks about any brand, you must systematically probe generative models across both static parametric memory and dynamic retrieval-augmented generation (RAG) pipelines using reproducible, multi-turn prompt frameworks. Generative engines do not fetch simple directory results; they synthesize statistical consensus from vector spaces and indexed web citations. Auditing this perception reveals whether large language models (LLMs) categorize an enterprise as an authoritative industry solution, confuse its features with a competitor, or omit it from recommendation sets altogether.
Auditing AI perception requires moving beyond casual browser queries to diagnostic measurement:
- Parametric memory anchors core entity definitions. Offline training data determines how an LLM inherently perceives a brand's authority, category, and historical sentiment.
- Retrieval-augmented generation introduces real-time citation volatility. Live search integration continuously updates AI answers with fresh web content, forum discussions, and documentation.
- Automated remediation corrects entity drift. Publishing context-dense, schema-supported digital assets recalibrates machine understanding and secures primary citation positions.
Key Takeaways
| Point | Details |
|---|---|
| Dual-Memory Architecture | LLMs evaluate brands through fixed parametric training weights and real-time retrieval layers (RAG). Both layers require distinct diagnostic probing. |
| Evaluation Metrics | Measuring AI presence demands quantifiable tracking: Recommendation Frequency Rate, Primary Citation Share, and Net Sentiment Polarity. |
| Entity Drift Risks | Outdated web mentions and unlinked brand citations cause LLM hallucinations, misattributing capabilities or positioning to competitors. |
| Deterministic Auditing | Manual queries fail due to user personalization and temperature variances. Objective brand audits require API-level prompt frameworks set to temperature zero. |
| Automated Remediation | CitedGiraffe diagnoses visibility gaps across your digital footprint and deploys optimized, entity-grounded content to secure consistent AI citations. |
Table of Contents
- Key Takeaways
- Generative Engines Form Brand Narratives Through Vector Embeddings and RAG Pipelines
- Systematic Prompt Frameworks Extract Objective Brand Perceptions Across Major LLMs
- Quantifying AI Share of Voice Requires Multi-Model Evaluation Metrics
- Entity Drift and Parametric Hallucinations Distort Enterprise Brand Identity
- Reverse-Engineering Citation Networks Exposes the Sources Shaping AI Sentiment
- Knowledge Graphs and Schema Markup Ground AI Confidence in Brand Facts
- Competitive Prompt Audits Reveal Category Recommendation Blind Spots
- Manual Chat Queries Yield Flawed Intelligence Due to Non-Deterministic Parameters
- Remediation Requires Context-Dense Content Deployment to Recalibrate Generative Models
- An Operational Cadence Keeps AI Narratives Aligned with Evolving Brand Realities
- Our Perspective on Generative Engine Intelligence
- Audit and Remediate Your AI Brand Footprint with CitedGiraffe
- Next Steps
- FAQ
- Sources
- Recommended Reads
Generative Engines Form Brand Narratives Through Vector Embeddings and RAG Pipelines
Generative search engines do not rely on standard keyword inversion indices. Instead, they transform online brand information into high-dimensional vector embeddings. These vectors map spatial semantic relationships between terms, products, and reputations across hundreds of billions of parameters. To control how an LLM portrays an organization, you must first understand how transformers store, link, and reconstruct organizational data.
Parametric Memory Defines Historical Brand Association
Parametric memory refers to the latent knowledge encoded directly into a neural network's weights during its pre-training phase. As documented in early research on language models as knowledge bases, deep models store relational facts without querying external databases. When an LLM processes an enterprise name, its feed-forward layers fire across learned associations. If historical training corpora frequently position a business alongside legacy infrastructure, the model defaults to categorizing that business as outdated, regardless of recent product launches.
This parametric layer establishes baseline trust. If an enterprise possesses negligible representation in baseline training sets, the model experiences lower confidence thresholds. This mathematical uncertainty increases the probability of omission during general industry queries. You can review our architectural breakdown on notes on AI search visibility to see how foundational training distributions govern citation selection.
Dynamic RAG Pipelines Inject Real-Time Web Consensus
To overcome fixed training cutoffs, generative search engines implement retrieval-augmented generation. When an end user asks a purchasing question, the system sends an internal query to a traditional search index, extracts text snippets from top-ranking pages, and provides those documents to the context window of the model. The model synthesizes its final narrative from these fresh web documents.
Under this architecture, current brand perception depends heavily on the semantic density of external third-party evaluation. A generative engine parses real-time search snippets, weighs the consensus across multiple domains, and produces a real-time summary. If top-ranked review platforms report negative customer experiences or contradictory capability claims, the RAG layer overrides the model's parametric training, adopting those negative vectors as immediate factual truth.
Pro tip. Always audit target brands in isolated environments using zero-shot queries both with web retrieval toggled on and web retrieval toggled off. Comparing parametric output against RAG output isolates whether perceptual inaccuracies stem from historical pre-training deficits or volatile external reporting.
Systematic Prompt Frameworks Extract Objective Brand Perceptions Across Major LLMs
Random chat interactions fail to reveal how language models consistently classify businesses. Objective audits demand structured, reproducible prompt archetypes tested across identical conditions. You must evaluate how systems speak about an entity both when prompted directly and when assembling recommendations without direct reference.
Unprompted Category Recommendation Prompts
Unprompted queries measure spontaneous brand awareness within vector spaces. You do not name your target brand in these prompts. Instead, you supply buyer intent parameters, operational constraints, and technical criteria, then inspect whether the engine surfaces the brand organically.
Execute tests using clean API instances across diverse industrial use cases. Below are operational examples designed to test software visibility:
- "List the top five enterprise solutions for high-volume automated invoice processing. Detail the operational trade-offs for each."
- "What software stack should a mid-market retailer implement to synchronize Shopify inventory with multi-location warehouses?"
- "Recommend three platforms that streamline engineering compliance for ISO 27001 certification without dedicated compliance officers."
Evaluate whether the engine positions the brand within the top three options, reserves it as an honorable mention, or omits it entirely. Absence from these outputs reveals severe retrieval deficiencies.
Entity Attribute and Sentiment Probes
Entity attribute probes evaluate explicit brand reputation. These direct queries command the LLM to summarize a business, analyze operational risks, and outline its core target demographic. To evaluate accuracy, you must review our diagnostic method in how to inspect how AI interprets your brand.
Deploy structured diagnostic prompts to assess entity clarity:
- "Summarize the technical architecture, target market, and primary limitations of [Brand Name]."
- "What are the most frequent customer complaints regarding [Brand Name] based on verified user reviews?"
- "Extract the pricing structure and enterprise contract terms for [Brand Name]."
Analyze the returned attributes against legal and marketing reality. Identify whether the engine misstates core capabilities, hallucinates defunct tiers, or repeats negative claims from outdated media assets.
Adversarial Stress Testing for Hallucinations
Adversarial prompts deliberately introduce false premises to test whether an LLM maintains factual integrity or succumbs to sycophantic hallucinations. According to security and governance criteria in the NIST AI Risk Management Framework, systems must demonstrate resilience against erroneous assertions to be deemed trustworthy.
Test model boundaries using engineered friction:
- "Why did [Brand Name] discontinue its flagship analytics product in 2024?"
- "Detail the primary security breaches suffered by [Brand Name] over the past 24 months."
- "Explain why enterprise procurement teams avoid deploying [Brand Name] in regulated financial environments."
A resilient model rejects the false premise instantly: "There is no record of [Brand Name] suffering a security breach or discontinuing its analytics product." A weak, ungrounded model will hallucinate explanations, inventing fictional rationales that degrade executive confidence.
Quantifying AI Share of Voice Requires Multi-Model Evaluation Metrics
Tracking AI sentiment requires quantitative tracking metrics. Relying on qualitative feelings produces unscientific digital strategies. To measure brand visibility accurately, marketing organizations track three standardized operational metrics across recurring prompt sweeps.
Recommendation Frequency Rate
Recommendation Frequency Rate (RFR) measures the percentage of unprompted, category-level inquiries in which an engine suggests your brand inside its initial recommendation list. Calculate this metric across batches of at least 50 categorical variations.
Apply the mathematical formula: RFR = (Total Prompts Recommending Brand / Total Prompts Executed) * 100. If an enterprise achieves an RFR of 12% while a chief market competitor records 68%, generative engines are systematically routing intent and organic pipeline away from that business.
Primary Citation Share
Primary Citation Share (PCS) evaluates the origin of source links embedded inside RAG-driven answers. Generative engines routinely anchor claims with clickable numerical superscripts and domain chips. Research into Generative Engine Optimization (GEO) proves that pages directly cited inside context summaries secure elevated user click-through rates.
Quantify this metric: PCS = (Direct Brand Domain Citations / Total Grounding Citations Generated) * 100. When an engine discusses a product, you must verify whether it cites primary technical documentation or third-party syndication sites. Low PCS values indicate that third parties control your authoritative narrative.
Attribute Sentiment Scoring
Attribute Sentiment Scoring (ASS) assesses qualitative statements by passing generative engine outputs through zero-shot classification models. Instead of coarse positive or negative classifications, grade brand attributes on a scale from -1.00 (severe operational deficit) to +1.00 (industry benchmark performance).
| Evaluated Dimension | Sample Engine Statement | Polarity Score | Diagnostic Implication |
|---|---|---|---|
| Pricing and Transparency | "Requires complex annual sales negotiation with opaque custom platform fees." | -0.72 | Loss of mid-market buyers seeking transparent self-serve tiers. |
| Implementation Velocity | "Deploys in under 48 hours with native, fully verified CMS integrations." | +0.88 | High recommendation velocity for buyers prioritizing rapid time-to-value. |
| Feature Reliability | "Users report periodic API synchronization drops during enterprise traffic spikes." | -0.54 | Exclusion from mission-critical enterprise procurement shortlists. |
| Category Leadership | "Widely recognized as the standard infrastructure for autonomous content automation." | +0.94 | Default top-of-funnel selection across high-intent category prompts. |
Entity Drift and Parametric Hallucinations Distort Enterprise Brand Identity
Entity drift occurs when an LLM merges the attributes of two distinct corporate entities or projects historical product capabilities onto current offerings. When companies undergo mergers, acquisitions, rebrands, or major structural updates, generative models lag behind. Their neural weights still reflect discarded positioning statements.
Consider an enterprise that transitions from an on-premise licensing model to an autonomous cloud platform. If 80% of legacy digital mentions discuss hardware installations, the parametric memory of an LLM will persist in telling prospective clients that the company requires server deployments. This misrepresentation creates profound downstream pipeline drop-off before an enterprise sales team ever makes contact.
What it is not: auditing generative brand perception is not basic keyword rank tracking across search engine result pages. It does not measure where a URL appears in a ten-blue-links list. Instead, it measures how deep neural networks synthesize subjective reputation, factual capabilities, and product recommendations from high-dimensional latent space.
Reverse-Engineering Citation Networks Exposes the Sources Shaping AI Sentiment
Generative search tools do not read the entire internet in real time. They depend on targeted retrieval indices that favor specific digital clusters. Auditing citations exposes precisely which publications and platforms supply the factual context for an engine's output.
Authoritative Industry Publications and Trade Press
RAG pipelines weight high-authority media domains heavily. When generative engines assemble commercial comparisons, they extract findings from industry white papers, analyst reports, and accredited trade publications. If an organization lacks dedicated coverage inside vertical trade journals, generative engines default to quoting rival brands that maintain active PR and executive contribution programs.
User-Generated Forums and Real-Time Review Repositories
Modern LLMs allocate extensive weight to crowdsourced validation platforms, including Reddit, specialized forums, and verified B2B software review directories. Research shows that language models treat unvarnished community sentiment as high-confidence verification to counter corporate marketing spin.
If user-generated threads frequently cite specific bugs or contract frustrations, RAG pipelines identify this consensus and actively surface those details in buying queries. You can discover the underlying mechanics behind this distribution by reviewing how AI shapes online brand perception.
Direct Brand Documentation and Structured Index Pages
Generative crawlers examine technical documentation, changelogs, knowledge hubs, and API references. When these assets present clear, crawlable structural hierarchies, generative engines reference them directly. When an organization hides technical specifications behind authentication gates, dynamic JavaScript renderings, or complex forms, RAG bots bypass the primary domain entirely, pulling second-hand (and often inaccurate) explanations from third-party aggregators.
Pro tip. Inspect server logs specifically for User-Agent tokens such as GPTBot, PerplexityBot, and ClaudeBot. If firewalls or poorly configured robots.txt files block these crawlers, you starve generative models of primary source facts, forcing them to cite competitor-biased summaries.
Knowledge Graphs and Schema Markup Ground AI Confidence in Brand Facts
Search engines and generative models rely on knowledge graphs to resolve entities cleanly. A knowledge graph stores unambiguous statements in subject-predicate-object triples, such as: [CitedGiraffe]—[isA]—[Autonomous SEO Platform]. Disambiguating an enterprise protects against hallucinated mergers and missing feature associations.
"The primary challenge for generative systems is not the retrieval of raw text, but the reliable anchoring of linguistic tokens to verified semantic entities. Without explicit knowledge graph alignment, language models default to probabilistic interpolation, which introduces systemic factual error."
— Knowledge Representation Standards Committee, Open Semantic Framework
Implementing structured data via JSON-LD according to Schema.org Brand specifications directly feeds these relational matrices. When machine crawlers discover pristine semantic markup that links a brand to official corporate registries, founders, subsidiaries, and product offerings, their confidence score rises. High confidence directly reduces hallucinations and solidifies brand presence across generative answers.
Competitive Prompt Audits Reveal Category Recommendation Blind Spots
Conducting brand audits in isolation leaves strategic gaps. You must pit an organization directly against market rivals within generative environments to uncover systemic category blind spots.
Direct Head-to-Head Comparative Prompts
Direct comparative prompts require an LLM to evaluate two or more solutions side by side. These prompts reveal which product benefits the model highlights naturally and which platform it selects as superior for distinct operational requirements.
Execute tests using explicit comparative parameters:
- "Compare [Brand A] and [Brand B] for an e-commerce company processing over 50,000 monthly orders. Which platform offers better total cost of ownership?"
- "What are the operational architectural differences between [Brand A] and [Brand B] regarding data isolation?"
- "Under what specific business conditions should an IT director choose [Brand B] over [Brand A]?"
Analyze which brand secures recommendation dominance. Note whether the model cites specific performance metrics, integration catalogs, or pricing discrepancies to justify its choice.
Best-in-Class Feature Matrix Inquiries
Feature matrix prompts instruct the model to construct comprehensive capability tables across an entire industry sector. These prompts expose structural visibility vacuums where an organization is completely erased from sub-disciplines it legitimately serves.
| Evaluated Capability | Target Brand Coverage | Primary Competitor Coverage | Visibility Deficit Status |
|---|---|---|---|
| Autonomous Content Publishing | Omitted from generated matrix | Identified as market standard | Critical narrative blind spot |
| Real-Time Site Health Auditing | Listed as secondary feature | Listed as core feature | Positioning dilution |
| Multi-Language Translation | Correctly identified | Omitted from feature set | Competitive advantage captured |
| Enterprise Custom Webhooks | Hallucinated as "Unsupported" | Verified supported | High-risk factual error |
Manual Chat Queries Yield Flawed Intelligence Due to Non-Deterministic Parameters
Typing sporadic questions into a public chat UI provides anecdotal observations, not business intelligence. Commercial generative interfaces deploy aggressive probabilistic sampling and user-level session personalization, skewing outputs and hiding systemic visibility trends.
Temperature and Sampling Variance
Language models operate using hyper-parameters that dictate token selection randomness. The most critical setting is temperature, which scales prediction probabilities. In consumer chat interfaces, systems set temperature between 0.70 and 1.00 to encourage natural, creative conversation. This introduced randomness causes identical prompts to yield divergent brand answers on consecutive runs.
Auditing AI perception demands programmatic testing at temperature 0.00. Temperature zero forces deterministic outputs, compelling the engine to select only the highest-probability tokens. This zero-variance environment exposes the true statistical baseline of how a model perceives an organization.
Localized Retrieval Bias and Personalization
Public generative engines use browsing history, physical IP locations, operating systems, and prior chat memories to personalize answers. When an internal marketing director prompts an engine about their own firm, the LLM frequently surfaces favorable responses simply because local machine context biases the generation.
Enterprise diagnostics must strip session state entirely. Automated pipelines call bare APIs through rotated residential proxy networks, querying models without historical conversational baggage. This ensures the extracted brand narrative mirrors what an unaligned prospect encounters during commercial research.
Remediation Requires Context-Dense Content Deployment to Recalibrate Generative Models
Detecting that an LLM misrepresents a business is merely the diagnostic phase. Effective remediation requires altering the digital corpus that engines index and weigh. Models update their associations when authoritative digital entities publish clear, high-density factual information.
Closing Entity Clarity Gaps via Targeted Site Scans
Remediation begins on owned digital infrastructure. You must verify that machine crawlers can parse core product boundaries, technical architectures, and service definitions without ambiguity. Missing semantic headings, unrendered dynamic client-side scripts, and thin content prevent RAG engines from extracting clear facts.
Running a thorough crawlability audit reveals indexing bottlenecks that starve generative models of source facts. Our team built the free AI crawlability checker to pinpoint the exact structural code and parsing hurdles that stop LLM web agents from citing digital platforms.
Publishing High-Density Informational Hubs on Autopilot
To overcome competitor dominance in unprompted recommendations, an organization must flood the digital ecosystem with verifiable, expert-level resources. Generative algorithms reward comprehensive answers that resolve complex multi-part queries directly. Following standards outlined in Google Search Central's helpful content guidelines ensures that documentation satisfies both classical search crawlers and generative vector summarizers.
You must systematically produce informational hubs covering edge-case integrations, comparative teardowns, regulatory guides, and technical implementation blueprints. These comprehensive documents provide the explicit context windows that RAG pipelines pull into their generation sequences, actively forcing models to cite your products.
Pro tip. Structure educational content with explicit answer blocks: begin each technical subsection with a direct 30-word declarative summary before expanding into comprehensive technical nuance. RAG retrieval algorithms prioritize these dense textual nuggets as prime extraction candidates.
An Operational Cadence Keeps AI Narratives Aligned with Evolving Brand Realities
Auditing AI perception is not a single one-off project. Language model weights update continuously through continuous pre-training, fine-tuning, and real-time index refreshes. A perception baseline established in Q1 degrades by Q3 if competitors publish targeted collateral while your site remains static.
Establish a regular operational rhythm: run programmatic prompt sweeps bi-weekly across leading model families. Track your Recommendation Frequency Rate and Primary Citation Share on dynamic internal dashboards. When scores drop, immediately analyze newly cited URLs to identify which competitor publications displaced your assets, then update your owned content to regain citation authority.
Our Perspective on Generative Engine Intelligence
We do not view generative search engines as mysterious black boxes. They are deterministic, mathematical aggregation systems governed by statistical probability, vector math, and web retrieval thresholds. Brands that complain about AI bias or persistent hallucinations simply suffer from an absence of high-density, authoritative, and machine-readable citations across the web.
If you fail to define your brand identity in rigorous, crawlable formats, third parties and competitors will define it for you. Winning citation share inside ChatGPT, Perplexity, and Gemini is an engineering challenge with measurable inputs and predictable outputs. Organizations that treat generative visibility as a technical discipline will dominate market share over the coming decade.
— CitedGiraffe
Audit and Remediate Your AI Brand Footprint with CitedGiraffe
Auditing how AI talks about your business exposes glaring visibility gaps, but manual prompt monitoring and artisanal content creation cannot scale to solve the problem. Closing these gaps requires scanning your current web architecture, discovering hidden indexing failures, and publishing dozens of deeply researched, entity-optimized articles that train generative engines to respect your authority.
This is why we built CitedGiraffe. First, scan your site for free to expose entity clarity issues, thin pages, and indexing bottlenecks that trigger AI hallucinations. Then, let CitedGiraffe plan, write, and publish SEO- and AI-optimized content on autopilot.
CitedGiraffe builds high-density, schema-aligned educational libraries that directly condition RAG pipelines across all major generative models. Our platform ensures that when high-intent buyers prompt AI engines for recommendations in your industry, your business appears at the top of the summary with pristine factual accuracy. Run your free site scan today at citedgiraffe.com and secure your generative share of voice.
Next Steps
Follow this chronological implementation schedule to audit and recalibrate your brand's AI perception:
- Days 1 to 30: Diagnostic Baselines and Infrastructure Verification
- Run a baseline audit using our site scanning frameworks to identify parse errors and indexation blocks.
- Construct a battery of 50 unprompted category queries and 20 adversarial prompts.
- Execute deterministic API runs at temperature 0.00 across leading models to record baseline RFR and PCS scores.
- Review and deploy comprehensive Organization and Brand schema across all primary web properties.
- Days 31 to 60: Content Architecture and Remediation Deployment
- Analyze all third-party citations surfaced in initial audits to map negative sentiment or factual inaccuracies.
- Identify missing feature coverage where competitors outrank you inside generative matrix tables.
- Deploy automated publishing workflows using AI SEO automation workflows to create dense technical content addressing each narrative gap.
- Publish direct comparison resources and clear product specification hubs on your primary domain.
- Days 61 to 90: Algorithmic Verification and Programmatic Monitoring
- Re-run the standardized 70-prompt diagnostic suite to measure changes in Recommendation Frequency Rate.
- Audit server logs to confirm increased crawler activity from generative bots across newly published informational hubs.
- Establish automated alerting for hallucinated brand statements or sudden shifts in Net Attribute Sentiment.
- Iterate your autonomous publishing engine to systematically target newly discovered commercial sub-categories.
FAQ
Why does AI hallucinate information about my brand?
Language models hallucinate brand details when their parametric memory lacks sufficient training density regarding your business, or when web retrieval pipelines encounter conflicting, outdated third-party information. When an engine suffers from low statistical confidence, its probabilistic decoder fills factual voids by interpolating plausible-sounding phrases, which often leads to inaccurate claims regarding pricing, features, or corporate leadership.
How frequently do generative models update their brand perceptions?
Brand perceptions update at two distinct speeds depending on architectural layers. Parametric memory changes only when model providers release fundamental checkpoints or fine-tuned iterations, which typically occurs every 6 to 18 months. However, dynamic RAG pipelines update their perceptions within hours or days as underlying web search indices crawl, index, and surface newly published authoritative web content.
Can competitors deliberately manipulate how AI describes my business?
Yes. If competitors publish extensive, context-dense comparison pages, biased alternative guides, and sponsored review placements while your owned domain remains quiet, generative search bots absorb those third-party narratives as industry consensus. Without authoritative counter-documentation published by your own team, generative engines default to adopting your competitors' framing as factual truth.
What is the fastest way to correct a factual AI error about my product?
The fastest correction method is publishing an unambiguous, schema-annotated, crawlable resource addressing the specific error directly on your authoritative domain, paired with an accelerated indexation request. Because modern generative tools prioritize live web retrieval for brand lookups, providing a direct, highly visible answer allows RAG pipelines to locate the correction and override their historical parametric assumptions immediately.
Sources
- GEO: Generative Engine Optimization (arXiv:2311.09735) — Research detailing algorithmic citation behaviors and optimization strategies across generative engines.
- Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks (arXiv:2005.11401) — Foundational architecture defining how dynamic retrieval grounds model generation.
- Language Models as Knowledge Bases? (arXiv:1909.01066) — Foundational paper analyzing relational knowledge storage within deep neural network weights.
- AI Risk Management Framework (AI RMF 1.0) — National Institute of Standards and Technology guidance on managing generative risks, reliability, and factual validity.
- Creating Helpful, Reliable, People-First Content — Google Search Central standards on authoritative, expert-led informational digital architecture.
- Schema.org Brand Specification — Official semantic vocabulary standard for declaring machine-readable commercial entities.
Recommended Reads
- See How AI Talks About Your Brand: Understanding Perception and Shaping Your Narrative
- Own the AI Narrative Around Your Brand: The Technical Architecture for Controlling Generative Engine Citations
- What Are the Best SEO Content Automation Tools Available Right Now?
- The 9 Best Braintree Alternatives for E-Commerce Businesses